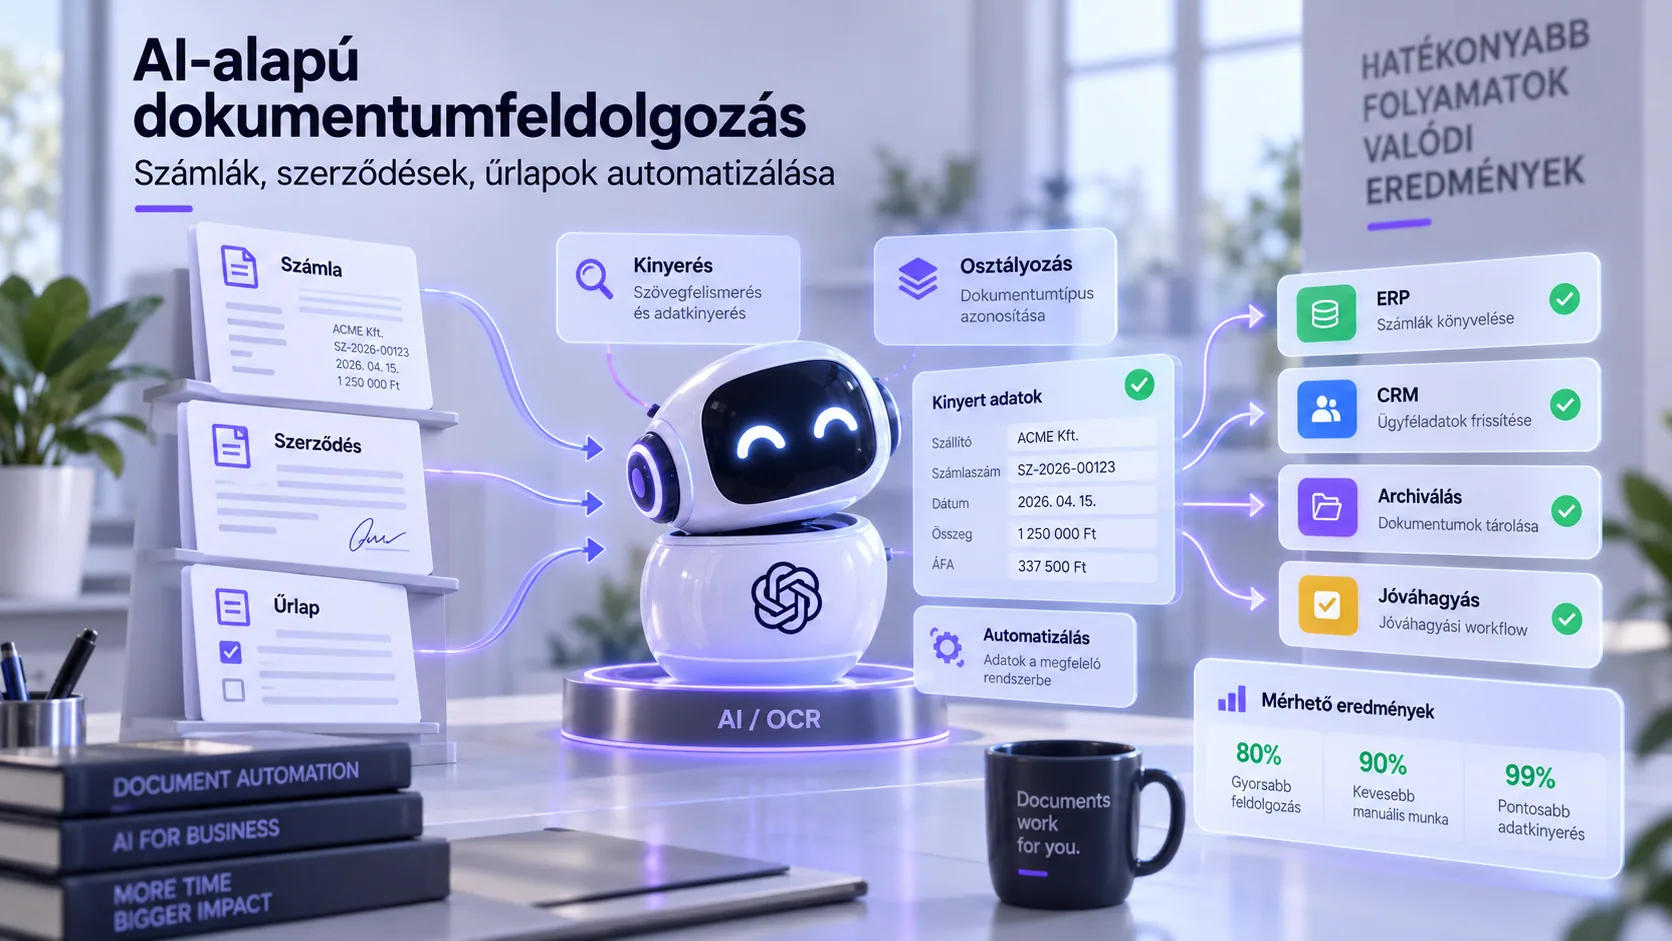
Invoices, contracts, and forms are three document types every company processes, and the cost of manual data entry is easy to measure: entering a supplier invoice by hand takes 4-8 minutes, pulling the key data out of a contract takes 15-30 minutes, and retyping a customer form takes 3-5 minutes. For a mid-sized company that adds up to 80-200 work hours a month, and the cost of errors — a mistyped amount, the wrong cost center, a missed deadline — is even higher.
In 2026 the combination of OCR and LLMs automates 70-90% of this work, but not the way demos show it. In a demo, a clean PDF turns into a neat JSON object. In production you get 12 suppliers with 12 different formats, scanned and skewed pages, handwritten notes, multi-page line items, and fields the model reads wrong with total confidence. Validation, human-in-the-loop review, and measurement are what make the difference.
This article describes the full pipeline from intake to ERP posting: choosing an OCR approach, JSON-schema extraction, field-level validation, human review only where it's needed, SAP/ERP integration, error-rate tracking, and ROI calculation. Code samples are in Python and TypeScript, and the schemas can be used directly.
The pipeline is not an agent: it's deterministic steps with one or two LLM calls. We covered when an agent model makes sense (for example, in supplier reconciliation) in AI agents for SMBs; here we stick with the workflow approach, because it's the better choice for 95% of invoice processing.
How is an OCR + LLM document processing pipeline structured?
Four layers, one after another, each with a measurable output.
Intake
OCR
LLM Extraction
Validation
HITL
ERP
1. Intake and preprocessing
Sources: email attachments, a shared folder, a supplier portal, or the ERP's own inbound queue. Preprocessing covers file-type detection, splitting multi-page PDFs, rotation correction, and duplicate filtering (hash + invoice number). This step is unglamorous, but it prevents 10-15% of errors before they happen.
Three cases:
| Input |
Method |
Note |
| Digitally generated PDF |
Native text layer (pdfplumber, PyMuPDF) |
Accurate, cheap, layout can be preserved |
| Scanned PDF / image |
OCR (Tesseract, cloud OCR, or a multimodal LLM) |
Quality depends on resolution; degrades below 300 dpi |
| Mixed (PDF with handwriting) |
Native + OCR on the image layer |
The handwritten note is often the most important piece of information |
In 2026, multimodal models can extract directly from an image, without an OCR step. That's a simpler pipeline, but it costs more per page, and errors are harder to trace because there's no intermediate text to check against. At high volume, classic OCR plus a text-based LLM is cheaper; at low volume and with complex layouts, the multimodal route gets you up and running faster.
The model receives the text (and layout information) and returns output that conforms to a JSON schema. The schema is not optional: without it, the output format changes from call to call, and validation becomes impossible.
4. Validation, human review, posting
The extracted JSON runs through rules and master-data matching; whatever fails goes to a human reviewer, whatever passes goes to the ERP. The ratio between these three outcomes is the health metric of the pipeline.
The schema describes three things: the fields, their types, and how uncertainty is flagged. The last one is the most commonly skipped, and the most useful.
# Invoice extraction schema (Pydantic) — input for the model's tool/structured output
from pydantic import BaseModel, Field
from typing import Literal
from datetime import date

class LineItem(BaseModel):
    description: str
    quantity: float
    unit: str | None = None
    net_unit_price: float
    vat_rate: Literal[0, 5, 18, 27] | None = Field(
        None, description="Hungarian VAT rate as a percentage; None if not legible."
    )
    net_amount: float

class FieldConfidence(BaseModel):
    field: str
    confidence: float = Field(ge=0, le=1)
    source_page: int | None = None
    note: str | None = Field(None, description="Why the field is uncertain (e.g. blurred, handwritten).")

class Invoice(BaseModel):
    supplier_name: str
    supplier_tax_id: str | None = Field(None, description="Format: 12345678-1-12 or HU12345678.")
    invoice_number: str
    issue_date: date
    due_date: date | None
    fulfillment_date: date | None
    currency: Literal["HUF", "EUR", "USD"]
    net_total: float
    vat_total: float
    gross_total: float
    line_items: list[LineItem]
    payment_reference: str | None = None
    confidences: list[FieldConfidence] = Field(
        description="Every field where confidence is below 0.9."
    )
Three principles for the schema:
- Don't ask for anything you can't validate. An "amount in words" field looks nice, but if you don't validate it, it's just noise.
- Allow
None. If you force the model to always return a value, it will make one up. A missing value is data; a made-up value is an error.
- Confidence per field, not per document. A 95% document-level confidence score hides the fact that the gross total is only 60% confident. Field-level values decide what goes to a human reviewer.
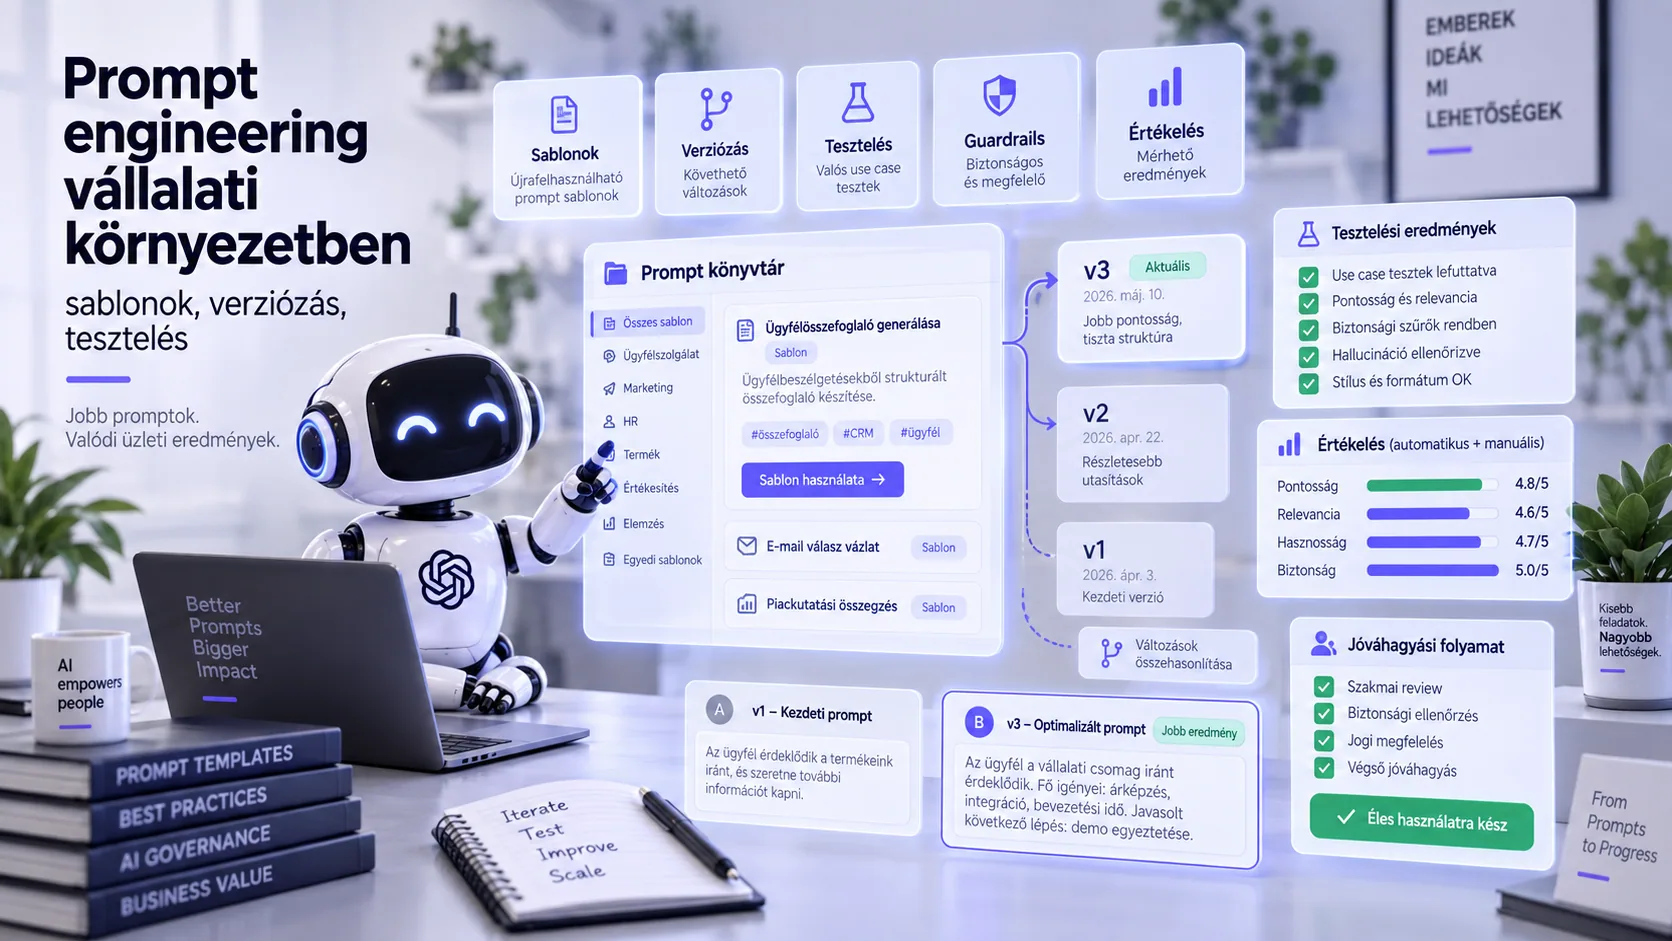
The prompt itself is short: role, schema, two or three rules (Hungarian date format, decimal comma, VAT rates), and one or two hard examples (few-shot). The template structure and versioning approach described in Prompt engineering in the enterprise applies here directly.
Note: Schema-constrained output (structured output) produces valid JSON, but not necessarily correct content. Even a syntactically flawless JSON object can have the net and gross amounts swapped. Validation is the next layer, not an option.
Contracts: how are they different from invoices?
An invoice is short, its format is stable per supplier, and its fields are numeric. A contract runs 5-60 pages, has a unique structure, and what you need to extract is partly text (termination conditions, penalty clauses), partly dates (expiry, the deadline for automatic renewal), and partly money (fees, indexation).
Three things change in the pipeline. Before extraction, you need sectioning: the model doesn't get the whole document, only the relevant chapters (based on the table of contents, or a first, cheap "which page is the termination clause on?" step), because feeding in all 60 pages at once is more expensive and less accurate. In the schema, text fields get a source quote alongside them: the model returns the original sentence and page number together with the extracted value, so on the review screen a person can verify it with one click instead of rereading the whole contract. And validation doesn't reconcile totals — it checks consistency: is the expiry date later than the effective date, is the notice period shorter than the contract term, does the fee's currency match the payment terms.
The payoff here doesn't come from time saved on data entry, but from missed deadlines avoided: a contract that auto-renews because nobody caught it within the termination window costs a full year's fee.
How do you validate, and when does a human need to step in?
Validation has three layers, from cheap to expensive. The goal: 70-90% of documents pass the first two layers, and only the remainder goes to a human.
1. Rule-based checks (free, instant)
// Field-level validation (TypeScript) — each rule produces an error message, not a throw
type Issue = { field: string; severity: 'error' | 'warn'; message: string };

export function validateInvoice(inv: Invoice, master: MasterData): Issue[] {
  const issues: Issue[] = [];
  const sumNet = inv.line_items.reduce((s, li) => s + li.net_amount, 0);

  if (Math.abs(sumNet - inv.net_total) > 1) {
    issues.push({ field: 'net_total', severity: 'error', message: 'Line-item total ≠ net total' });
  }
  if (Math.abs(inv.net_total + inv.vat_total - inv.gross_total) > 1) {
    issues.push({ field: 'gross_total', severity: 'error', message: 'Net + VAT ≠ gross' });
  }
  if (inv.supplier_tax_id && !isValidHuTaxId(inv.supplier_tax_id)) {
    issues.push({ field: 'supplier_tax_id', severity: 'error', message: 'Tax ID checksum is invalid' });
  }
  if (inv.due_date && inv.due_date < inv.issue_date) {
    issues.push({ field: 'due_date', severity: 'warn', message: 'Due date is before the issue date' });
  }
  if (!master.suppliers.byTaxId(inv.supplier_tax_id)) {
    issues.push({ field: 'supplier_name', severity: 'warn', message: 'Unknown supplier in master data' });
  }
  for (const c of inv.confidences) {
    if (c.confidence < 0.8) {
      issues.push({ field: c.field, severity: 'warn', message: `Low confidence (${c.confidence})` });
    }
  }
  return issues;
}
Tax ID checksum validation, matching totals, date ordering: these catch 40-60% of errors at zero LLM cost.
2. Master-data matching
Is the supplier in the ERP master data, is the PO number among the open orders, does the bank account number match the master record (invoice-fraud protection). This layer reads from the ERP, so the integration is needed here already, not just for posting.
3. Human-in-the-loop
Anything flagged with an error-level issue, or where a critical field's confidence is below the threshold, goes to a human reviewer. The interface's core idea: next to the extracted field sits a crop of the original document, corrections take one click, and the correction feeds back into the eval set.
The HITL rate is the metric to watch live. It starts at 30-40%, and drops to 10-15% after three months if corrections flow back into the prompt and the eval set. If it doesn't come down, the pipeline isn't learning — it's just generating work.
How do you integrate with the ERP or SAP?
Extracted and validated data is only worth something once it's in the ERP. Three integration patterns, in increasing order of complexity:
| Pattern |
When |
Risk |
| File export (CSV/XML) to the ERP's import folder |
Small ERP, no API |
No confirmation; errors are caught inside the ERP |
| REST / OData posting |
SAP S/4HANA, modern ERPs |
Needs authorization, idempotency, an error queue |
| Intermediate staging table + ERP-side processing |
High volume, strict controls |
Two systems, two error lists |
In SAP, the incoming invoice (Supplier Invoice) is posted through an OData service; cost-center and G/L account assignment for the line items either comes from the extraction (if the invoice carries a PO number) or from a rule (supplier → default cost center). Our logistics SAP integration case study runs exactly this pattern: OData interface, staging, confirmation.
Two practical rules:
- Idempotency. The same invoice posted twice must not be booked twice. Check the invoice number + supplier tax ID key before posting.
- Error queue. If the ERP rejects a document (closed period, missing master data), it must not get lost: it goes into a separate queue for human handling, together with the error message.
We cover the ERP-side integration questions (authorization, transports, test systems) in our enterprise systems service and in The common pitfalls of S/4HANA migration.
Invoice
Validated JSON
SAP OData Posting
Confirmation
How do you measure the error rate, and what's a good number?
"It works" is not a metric. Four numbers we track from day one:
| Metric |
Definition |
Target after 3 months |
| Field-level accuracy |
Correct fields / all fields, on the eval set |
≥ 97% on critical fields (amount, tax ID, invoice number) |
| Document-level STP |
Posted without human touch / all documents |
70-85% |
| HITL rate |
Sent to a human / all documents |
10-20% |
| Turnaround time |
From intake to posting |
< 1 hour automated, < 1 day for HITL |
The eval set: 100-200 real documents, proportionally by format (if there are 12 suppliers, at least 8-10 documents from each), with manually verified expected JSON. It reruns after every prompt or model change. The methodology is the same one we described in Defending against LLM hallucinations, except here the metric is field-level match, not text quality.
Watch out: Look at field-level accuracy broken down by format, too. A 96% average can hide the fact that accuracy on one supplier's invoices is only 75%, because the model consistently swaps the net and gross columns. The per-format breakdown shows you where you need a few-shot example.
What GDPR considerations apply to document processing?
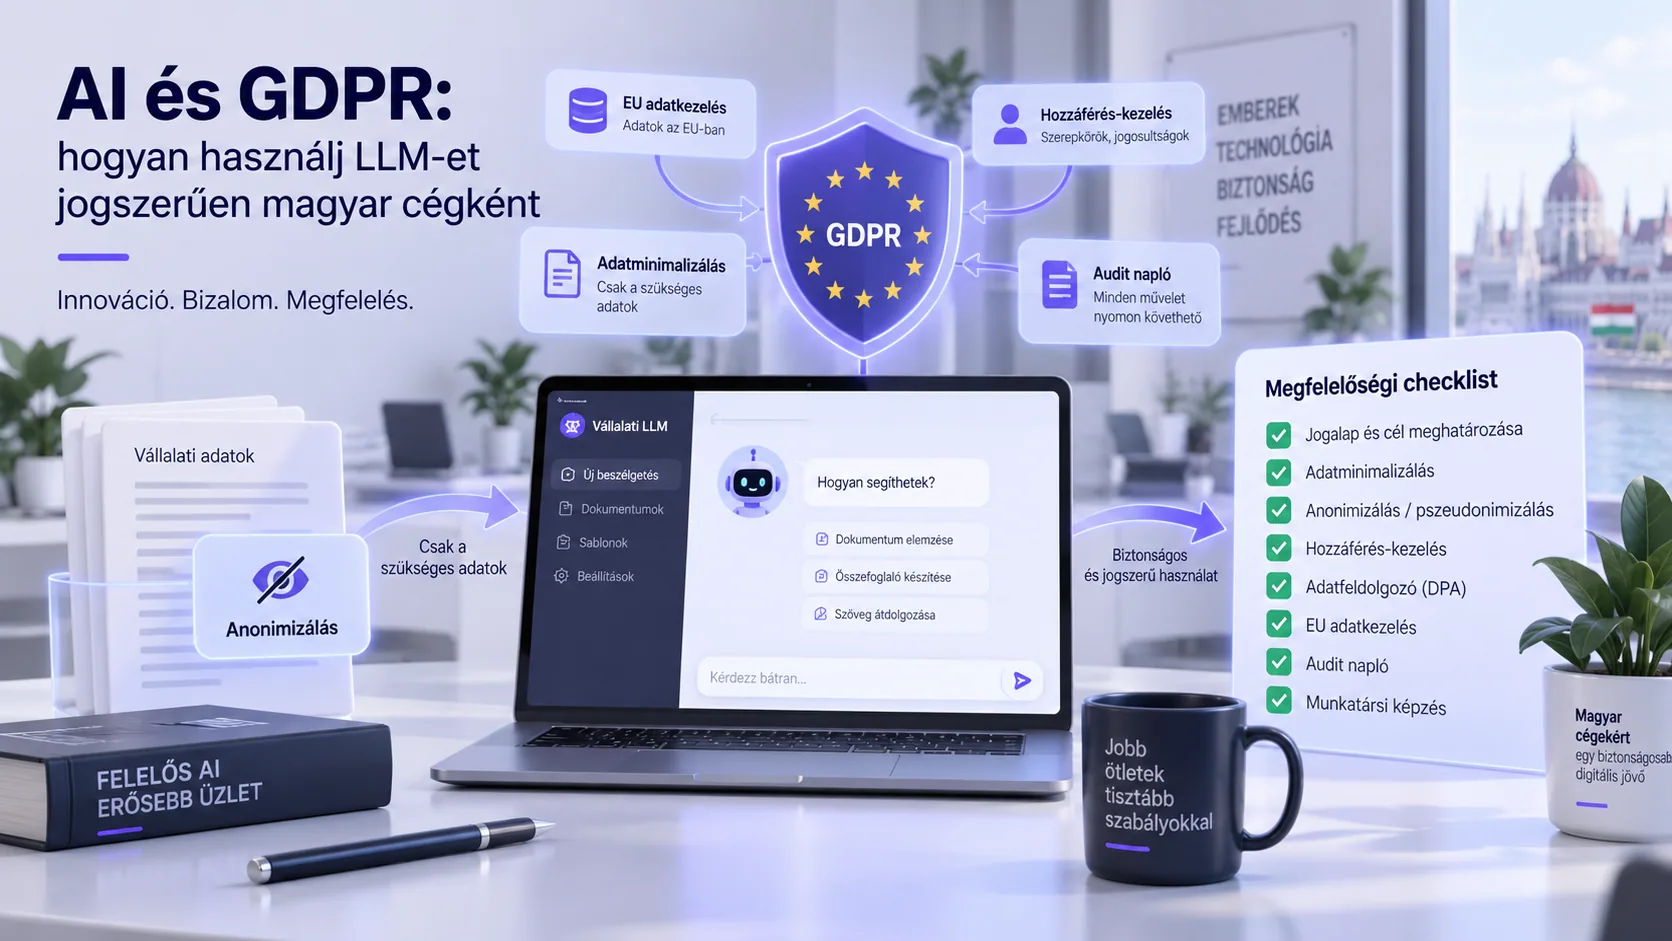
Invoices and contracts carry personal data: a contact person's name and email, a signatory, a sole trader's details. That makes the LLM provider a data processor, and the following are required:
- A data processing agreement (DPA) with the provider, including a training opt-out. In 2026, the major providers' business terms already include this.
- Data minimization. The model should only receive what's needed for extraction. The pipeline can mask anything not needed before submission (for example, the bank account number, if master-data matching happens ERP-side anyway).
- Retention. Provider-side prompt retention (0-30 days, depending on the terms) should be documented in your privacy notice.
- EU region for personal data, if internal policy or the client requires it.
On the other side of the pipeline: only people whose role requires it should be able to see the document on the review screen, and logging should record who corrected what. We cover the details (legal basis, legitimate-interest balancing, pseudonymization) in AI and GDPR for Hungarian companies.
How much does a document processing system save?
A concrete, order-of-magnitude calculation for a company processing 1,500 supplier invoices a month:
Current cost:
  1,500 invoices × 6 min = 150 hours / month
  150 hours × 5,500 HUF (fully loaded hourly rate, accounting assistant) = 825,000 HUF / month
  + error correction, late-payment interest, double-booked items: estimated 100,000-150,000 HUF / month

Automated pipeline (after month 3, 80% STP, 15% HITL, 5% error queue):
  LLM + OCR cost: 1,500 × ~15 HUF = ~25,000 HUF / month
  HITL: 225 invoices × 2 min = 7.5 hours × 5,500 HUF = ~41,000 HUF / month
  Error queue: 75 invoices × 6 min = 7.5 hours = ~41,000 HUF / month
  Operations, eval maintenance, monitoring: 80,000-120,000 HUF / month
  Total: ~200,000-230,000 HUF / month

Savings: ~700,000-750,000 HUF / month (+ most of the error cost)

Implementation (discovery, pipeline, HITL interface, SAP integration, eval): HUF 3-5 million
Payback period: 5-7 months
This calculation is sensitive to two factors: volume (below 300 invoices a month, the implementation rarely pays back within a year) and the STP rate (if it's still under 50% after 3 months, either the formats or the schema need work). For contracts, the formula is different: fewer documents, but 15-30 minutes saved per document, and deadline monitoring (expiry, termination window) is a cost avoided in its own right.
Frequently asked questions
How accurate is AI-based invoice processing?
With a well-built pipeline (OCR + JSON-schema extraction + rule-based validation), accuracy on critical fields is above 97% after 3 months, and 70-85% of invoices post without human touch. The rest goes to a human reviewer, where accuracy is effectively 100% because a person checks it.
Do I need OCR if I use a multimodal LLM?
Not necessarily: multimodal models extract directly from images. At high volume, OCR plus a text-based LLM is cheaper and errors are easier to trace; at low volume and with complex layouts, the multimodal route gets you up and running faster. The decision comes down to accuracy measured on your own documents and the cost per page in HUF.
In SAP S/4HANA, through an OData service (the Supplier Invoice API), with idempotent posting and an error queue; for older or smaller ERPs, through a staging table or file import. Integration makes up 30-40% of the project, which is why ERP-side authorization and test systems are the first question in discovery.
Is processing invoices with an LLM GDPR-compliant?
Yes, provided there's a data processing agreement with the provider that includes a training opt-out, the model only receives the data needed for extraction, the retention period is documented in your privacy notice, and you use EU-region processing for sensitive cases. On the review interface, access is role-based and logged.
Closing thoughts
In 2026, document processing is one of the AI projects with the most reliable payback, because the input is unstructured but the output is precisely definable, and the manual cost is measurable. What separates a demo from a production system isn't the model — it's the schema, the validation, the HITL interface, and the eval set. Without them, the pipeline breaks the first time a format changes, and nobody notices.
The practical order: collect 100-200 real documents, proportionally by format; write the schema allowing None and with field-level confidence; build rule-based validation both before and after the LLM step; and track the STP and HITL rates from day one. Plan the ERP integration during discovery, not at the end.
Official sources
Related articles: AI agents for SMBs in 2026, Prompt engineering in the enterprise, Defending against LLM hallucinations.
If hundreds of invoices, contracts, or forms go through manual entry at your company every month, book a 30-minute call: we'll go through your document types, your ERP-side options, and the expected STP rate, and tell you whether it pays off. We build the pipeline within your own environment as part of our AI automation projects — your documents never leave your systems.