LLMs hallucinate — that is not a bug, it is how generative models work. Autoregressive models choose every token based on a probability distribution, with no assurance that the choice is factually correct. A production AI system should not promise that hallucination never happens (no one can promise that) — it should promise that the hallucination rate is measurable and kept at an acceptable level.
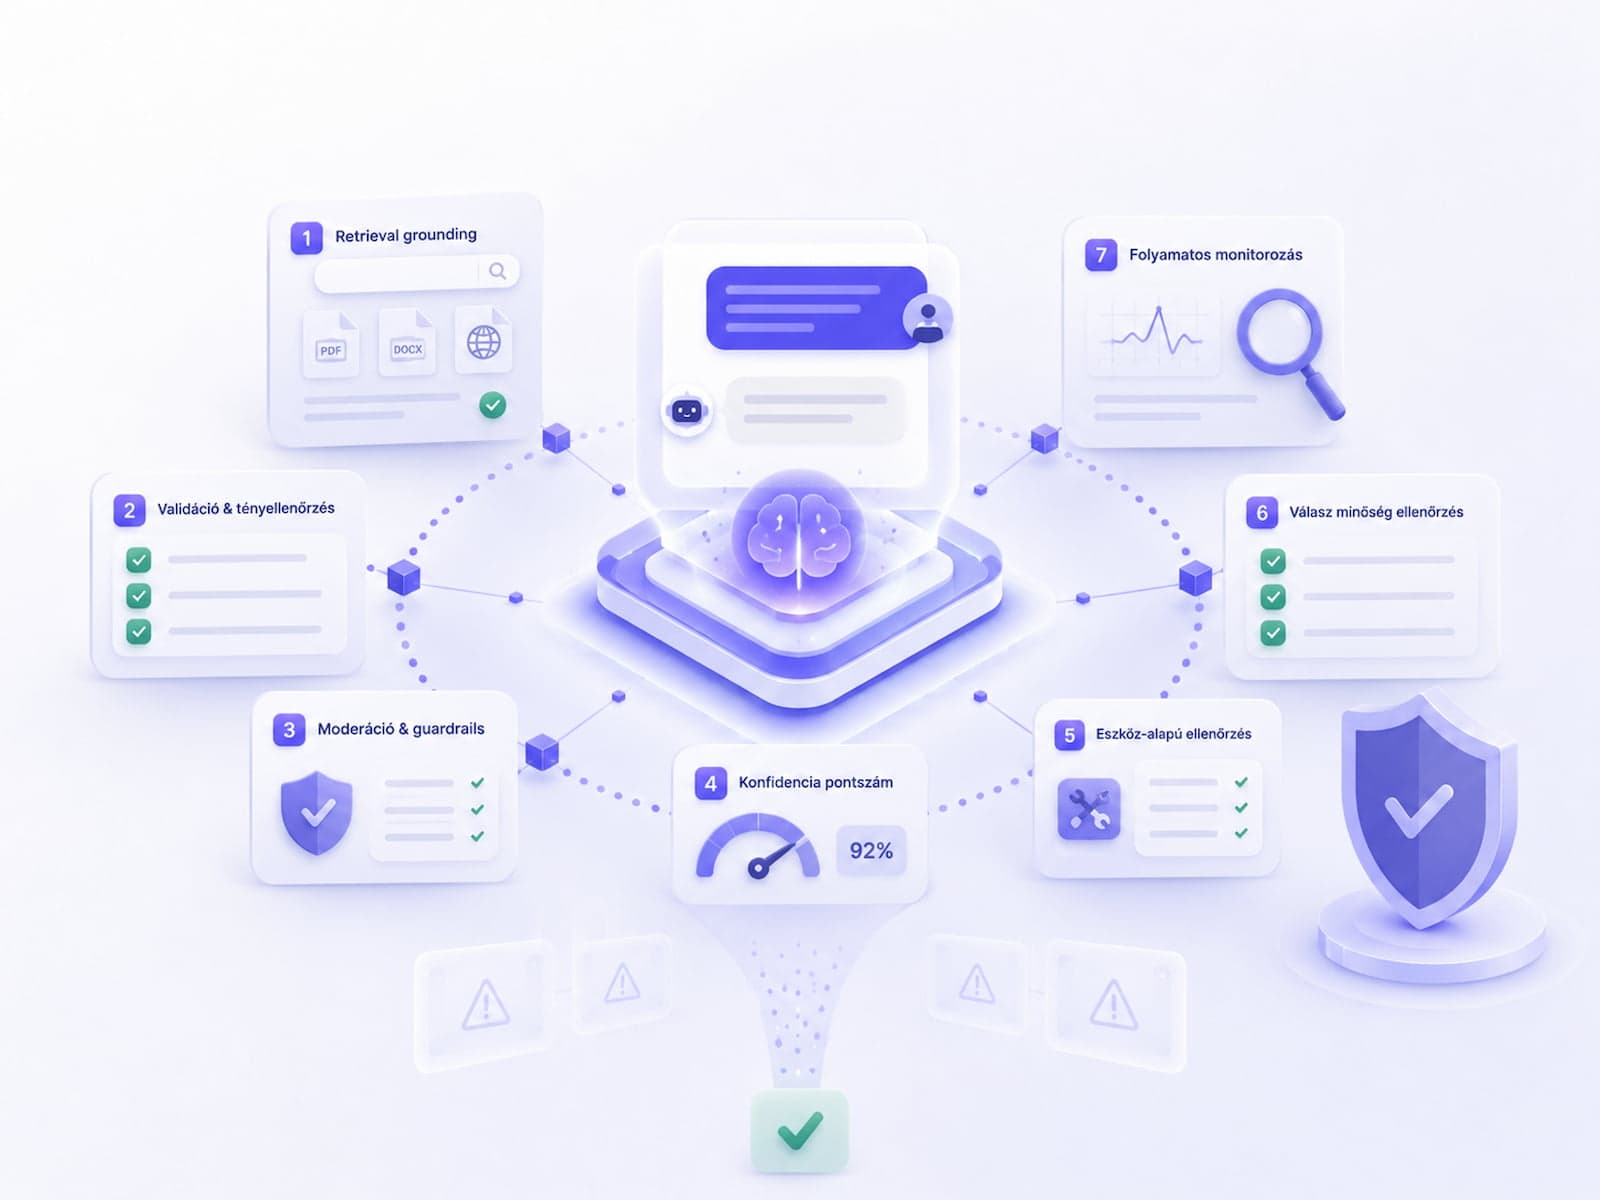
This article walks through seven proven defenses that, combined, raise accuracy from a 60-70% baseline to 92-95% in most domains. These techniques stack — they are not alternatives to each other, they are complements.
What hallucination is and where it shows up
"Hallucination" is an umbrella term covering three distinct phenomena:
- Factual hallucination: the model states a fact that is not true. E.g., "The 2024 delivery SLA sets the Q4 churn threshold at 8%" — while the document actually says 12%.
- Source hallucination: the model cites a source that does not exist. E.g., "According to policy clause 4.2.1..." — but there is no clause 4.2.1.
- Reasoning hallucination: the model draws an incorrect conclusion from correct data. E.g., "Since the annual leave allowance is 25 days and X has already used 24, they are not entitled to leave this week" — but the policy actually specifies 30 days.
Each of the three calls for a different defense. Factual hallucination is addressed by RAG and citations, source hallucination by schema validation and source verification, and reasoning hallucination by self-consistency checks and human-in-the-loop review.
Where it shows up in production
In our experience, hallucination shows up most often in four situations:
- Out-of-domain query — the user asks a question for which there is no source in the vector DB. The model "fills the gap" with a fabricated answer.
- Partial source — the source chunk only partially contains the answer, and the model extrapolates.
- Conflicting sources — two chunks give different information; the model picks one or blends them together.
- Long-tail edge case — an unusual, rare question that the training data barely covered.
The seven defenses below are designed around these four scenarios.
1. Context grounding (RAG)
The most effective technique: never let the LLM generate freely — always give it context. Retrieval-Augmented Generation works by pulling relevant documents out of the vector DB, passing them in the system prompt, and explicitly instructing the model to "answer only from the sources."
The basic pattern
system_prompt = """
You are a documentation assistant.
ONLY answer based on the SOURCES below.
If the sources don't contain the answer, say "I don't know".

SOURCES:
[1] {source_1}
[2] {source_2}
[3] {source_3}

Question: {user_query}
"""
The "answer only from sources" instruction alone is no guarantee — but it raises precision by 20-30 points over baseline. For a detailed RAG pipeline implementation, see Building a RAG chatbot.
Negative prompting
The model needs explicit permission to output "I don't know." LLMs default toward being "helpful," which pushes them to answer every question. That tendency has to be overridden:
"""
IMPORTANT:
- If the sources don't contain the answer, output EXACTLY: "I could not find a clear answer in the documents."
- Do NOT speculate or guess.
- Do NOT use general knowledge from your training data.
- Do NOT combine information from sources unless they explicitly support each other.
"""
These anti-instructions cut the factual hallucination rate by 15-20 pp.
Source attribution required
Add an explicit requirement in the system prompt that every answer must cite at least one source. If there is no source, the answer is not permitted.
Measurable impact
| Setup |
Factual accuracy (eval set) |
| LLM only (no RAG) |
45-55% |
| RAG with naive prompt |
70-78% |
| RAG with grounding instructions |
85-92% |
2. Citation requirement
Don't just ask the LLM for an answer — ask for a source identifier too. This has two benefits: (1) the LLM is less likely to make things up, because it knows it has to provide a source reference, and (2) the user can verify the answer.
Implementation
system_prompt = """
For EVERY factual claim in your answer, cite the source ID in square brackets, e.g. [1].
If you cannot cite a source for a claim, do not make the claim.
If a sentence has no citation, you are not allowed to write it.

Format example:
"The annual leave allowance is 25 days [2]. It is issued every year on January 1st [2, 5]."
"""
Post-processing validation
import re

def validate_citations(response: str) -> dict:
    sentences = re.split(r"(?<=[.!?])\s+", response.strip())
    factual_sentences = [s for s in sentences if not is_intro_or_summary(s)]

    no_citation = [
        s for s in factual_sentences
        if not re.search(r"\[\d+(?:,\s*\d+)*\]", s)
    ]

    return {
        "total_sentences": len(factual_sentences),
        "uncited_sentences": no_citation,
        "passes": len(no_citation) == 0,
    }
If there are any uncited_sentences, the response does not pass the quality gate. It either gets regenerated or handed off to a human.
Measuring citation frequency
In a well-tuned system, 80-90% of sentences carry a citation. If that figure drops below 50%, the model is ignoring the instruction — the prompt needs refining.
Tip: A side effect of requiring citations is a more concise answer. LLMs like to generate long, "expert-sounding" explanations — 60-70% of that content ends up without a citation. Enforcing citations automatically trims responses down to what can actually be sourced.
3. Temperature and top_p tuning
The temperature and top_p parameters control how "creative" the model gets. A higher value means more variability and a higher hallucination risk. A lower value means more deterministic output and less hallucination.
The two parameters
temperature (0.0-2.0): how flat the logit distribution is. 0 always picks the top-1 token; 2 is close to uniform.top_p (0.0-1.0): the cumulative probability cutoff. 0.1 means the model only samples from the top 10% probability mass of tokens.
Adjust only one of them at a time and leave the other at its default — OpenAI's documentation recommends the same.
Recommendations by use case
| Use case |
Recommended temperature |
Recommended top_p |
| RAG factual Q&A |
0.0-0.2 |
0.1-0.3 |
| Doc summarization |
0.1-0.3 |
0.2-0.4 |
| Tutorial / explanation |
0.2-0.4 |
0.3-0.5 |
| Marketing copy |
0.5-0.7 |
0.6-0.8 |
| Brainstorming, divergent |
0.7-1.0 |
0.8-0.95 |
| Code generation |
0.0-0.2 |
0.1-0.3 |
A note on temperature=0
temperature=0 does not ensure deterministic output — token tie-breaks can still be stochastic, and LLM providers don't always deliver full determinism. The seed parameter (supported by OpenAI) helps, but not completely.
Code example
response = openai.chat.completions.create(
    model="gpt-4o",
    messages=[...],
    temperature=0.1,
    seed=42,  # for reproducibility
    max_tokens=500,
)
4. Self-consistency checking
For critical answers, run generation with 3 different seeds (temperature=0.3, three different random seeds). If all three say the same thing, confidence is high. If they diverge, flag it to the user or fall back to human-in-the-loop.
Implementation
def self_consistency_check(prompt: str, seeds: list[int] = [42, 100, 7]) -> dict:
    responses = []
    for seed in seeds:
        response = llm.generate(
            prompt,
            temperature=0.3,
            seed=seed,
            max_tokens=500,
        )
        responses.append(response)

    return {
        "responses": responses,
        "consistent": all_semantically_equivalent(responses),
        "majority_vote": majority(responses),
    }
all_semantically_equivalent can be measured with a second LLM call (a "judge" LLM that checks whether the three answers essentially say the same thing), or with simple substring overlap (a ROUGE-L score above 0.85).
Cost and when to use it
This costs 3x the API calls of a single generation. Reserve it for critical decisions (medical, legal, financial). For a simple FAQ chatbot, it is overkill.
Aggregation strategy
If the 3 answers diverge:
- Majority vote: if 2 agree and 1 differs, go with the majority.
- Hedge: if all three differ → "There are multiple valid interpretations of this answer. [source citation for each case]."
- Escalate: in critical contexts, hand off to a human immediately.
5. Output validation (JSON schema, regex)
When the LLM outputs structured data (a category, a score, a JSON object), validate it against a schema. OpenAI's JSON mode and Anthropic's tool use already enforce a schema at the API level, but post-validation is still necessary.
Pydantic + OpenAI
from pydantic import BaseModel, Field
from typing import Literal
import openai

class LeadClassification(BaseModel):
    category: Literal["technical", "commercial", "complaint", "partnership"]
    urgency: int = Field(ge=0, le=100)
    confidence: float = Field(ge=0.0, le=1.0)
    follow_up_draft: str = Field(max_length=500)
    reasoning: str = Field(max_length=200)

response = openai.chat.completions.create(
    model="gpt-4o",
    messages=[...],
    response_format={"type": "json_object"},
    temperature=0.1,
)

try:
    result = LeadClassification.model_validate_json(
        response.choices[0].message.content
    )
except ValidationError as e:
    # Retry, fallback, or human queue
    handle_invalid_output(e)
Structured Output (OpenAI 2024+)
In 2024 OpenAI introduced the Structured Outputs feature alongside response_format. Strict schema compliance is now enforced at the provider level:
response = openai.chat.completions.create(
    model="gpt-4o-2024-08-06",
    messages=[...],
    response_format={
        "type": "json_schema",
        "json_schema": {
            "name": "lead_classification",
            "schema": LeadClassification.model_json_schema(),
            "strict": True,
        },
    },
)
With strict: True, schema violations are essentially eliminated.
Retry strategy
If validation fails, retry up to 2 times. On the second retry, explicitly surface the previous error in the system prompt:
def call_with_retry(prompt, schema, max_retries=2):
    for attempt in range(max_retries + 1):
        response = llm.generate(prompt)
        try:
            return schema.model_validate_json(response)
        except ValidationError as e:
            if attempt < max_retries:
                prompt = augment_prompt_with_error(prompt, e)
            else:
                return fallback_default()
Measurable impact
Without schema validation, the malformed-JSON rate runs 3-8% in production. With schema validation, it drops below 0.5%.
6. Confidence scoring + threshold
Ask the LLM to produce a confidence score for its own answer. It is not flawless — LLMs tend to be overconfident — but it often does flag edge cases.
System prompt
After your answer, output a confidence score on a scale of 0-100:
- 90-100: Sources clearly and completely support the answer
- 70-89: Sources support, but some inference needed
- 50-69: Partial support, some details missing
- 30-49: Weak support, significant gaps
- <30: Insufficient sources, answer is uncertain

Output format:
ANSWER: [your answer with citations]
CONFIDENCE: [0-100]
REASONING: [why this confidence level]
Threshold-based routing
def route_by_confidence(response: dict) -> str:
    if response["confidence"] >= 80:
        return "auto_send"
    elif response["confidence"] >= 50:
        return "auto_send_with_flag"  # "Please verify:"
    elif response["confidence"] >= 30:
        return "human_review_queue"
    else:
        return "explicit_not_found"
This four-tier routing works best based on production experience. The "flag" tier is useful for marketing copy — at 60% confidence the LLM is often correct, just not fully certain.
Calibration check
At 80-90% confidence, LLMs often deliver only 60-70% accuracy — they are overconfident. This needs manual calibration. Typical tuning looks like this:
| Model confidence |
Actual accuracy |
Use case |
| 90-100 |
88-95% |
Auto-send |
| 70-89 |
75-85% |
Auto-send (flagged) |
| 50-69 |
55-70% |
Human review |
| 30-49 |
30-50% |
Explicit "not found" |
| <30 |
<30% |
Explicit "not found" |
This is measurable against the eval set, and thresholds should be tuned accordingly.
Tip: A confidence score does not replace the eval set. A model can report 95% confidence while its real accuracy is 70%. The two numbers need to be tracked separately.
7. Human-in-the-loop fallback
Even the six techniques above will not get you to 100%. Design a flexible escalation path:
The four-tier model
┌─────────────────────────────────────────────────────────┐
│ High confidence + citation + schema valid                │
│   → Auto-response                                        │
├─────────────────────────────────────────────────────────┤
│ Medium confidence (50-70) + valid                         │
│   → Auto-response, flag "Please verify"                  │
├─────────────────────────────────────────────────────────┤
│ Low confidence (<50) OR uncited sentences                 │
│   → Human review queue                                    │
├─────────────────────────────────────────────────────────┤
│ No sources found OR validation fails 2x                   │
│   → Explicit "information not found" + ticket opened      │
└─────────────────────────────────────────────────────────┘
Implementation
def handle_query(query: str) -> dict:
    response = generate_with_rag(query)

    if not response["citations"]:
        return {"action": "queue", "reason": "no_citations"}
    if not response["schema_valid"]:
        return {"action": "queue", "reason": "invalid_schema"}
    if response["confidence"] < 50:
        return {"action": "queue", "reason": "low_confidence"}
    if response["confidence"] < 70:
        return {"action": "auto_with_flag", "flag": "verify_recommended"}
    return {"action": "auto", "response": response["text"]}
Queue management
The human-review queue typically runs 5-15% of total traffic. The client's internal team (sales, support) reviews quickly — 30-60 seconds per case on average — and the lessons learned feed into expanding the eval set.
Feedback loop
Answers rejected or corrected during human review go to two places:
- Eval set expansion: this is now a known "hard" case.
- Prompt fine-tuning: once 5+ similar errors show up, the exception gets built into the system prompt.
The eval set — the key to everything
None of the seven techniques can be measured without an eval set. You need at minimum 50-200 manually labeled input-output pairs, balanced across the use case distribution.
Minimum structure
eval_dataset = [
    {
        "id": "eval_001",
        "query": "What does the 2024 delivery SLA say about Q4 churn?",
        "expected_keywords": ["Q4", "churn", "12%"],
        "expected_citation": ["doc_42_chunk_3"],
        "category": "factual_extraction",
        "difficulty": "easy",
    },
    {
        "id": "eval_002",
        "query": "When was the delivery SLA last changed?",
        "expected_keywords": ["no clear answer"],  # negative case
        "expected_citation": [],
        "category": "out_of_domain",
        "difficulty": "medium",
    },
    # ...
]
Metrics
| Metric |
Definition |
Target |
| Faithfulness |
Whether the answer relies only on the sources |
95%+ |
| Answer relevancy |
Whether the answer addresses the question asked |
90%+ |
| Context precision |
Whether the retrieved chunks are relevant |
80%+ |
| Citation accuracy |
Whether citations point to real sources |
99%+ |
| Schema validity |
Whether the JSON output conforms to the schema |
99%+ |
| Confidence calibration |
Correlation between confidence and accuracy |
±10% |
The Ragas framework calculates these metrics automatically.
Maintenance
Maintaining the eval set is a daily task:
- New edge cases → eval set (5-10 new cases per week is typical during hyper-care).
- Negative user feedback → eval set — a "bad answer" report is always a starting point.
- Prompt changes → regression-test against the eval set. If accuracy falls below the threshold → blocked deploy.
In the CI/CD pipeline:
# .github/workflows/eval.yml
on:
  pull_request:
    paths:
      - "prompts/**"
      - "src/llm/**"
jobs:
  eval:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - name: Run eval suite
        run: python eval/run.py --threshold 0.92
      - name: Block on failure
        if: failure()
        run: exit 1
Measurement frameworks — Ragas and friends
The open-source eval frameworks that matured in 2025-2026:
- Ragas: RAG-specific metrics. Python-based, built on the OpenAI/Anthropic APIs. The default choice.
- DeepEval: A pytest-style assertion framework for LLM output. Good for CI integration.
- promptfoo: A web-UI prompt-comparison tool. Good for the manual tuning phase.
- OpenAI Evals: OpenAI's own framework, a bit more cumbersome.
On Corevanix projects we use a combination of Ragas and DeepEval: Ragas for quality metrics, DeepEval for CI-blocking assertions.
Summary — combining the seven techniques
The seven techniques do not replace one another — they work together. In a production-grade system, this typically looks like:
| Technique |
Cost impact |
Accuracy impact |
Mandatory? |
| 1. Context grounding (RAG) |
$$$ |
+25-30 pp |
Mandatory |
| 2. Citation requirement |
$ |
+5-8 pp |
Mandatory |
| 3. Temperature tuning |
$0 |
+3-5 pp |
Mandatory |
| 4. Self-consistency |
$$$$ |
+5-10 pp |
Critical cases only |
| 5. Schema validation |
$ |
+2-3 pp |
Mandatory for structured output |
| 6. Confidence scoring |
$ |
+5-8 pp (with routing) |
Strongly recommended |
| 7. Human-in-the-loop |
n/a |
+10-15 pp (effective) |
Mandatory in the first months |
The full stack delivers a +60-70 pp improvement over baseline. That often means the jump from "45% accuracy" to "92%+ accuracy."